Website speed is how quickly your website feels usable to people, not just how fast your server replies. It shapes user patience, page engagement, conversions, and long-term search visibility. That is why improving website speed often starts with measuring real user experience and then fixing the bottlenecks you can actually control.
In this complete guide, you will learn what website speed measurements mean, which indicators to prioritize, and how to diagnose causes without guessing. You will also get a practical path: measure → interpret metrics → find bottlenecks → prioritize fixes → verify with repeat tests. By 2026, performance expectations have become more user-focused, with modern delivery patterns and Core Web Vitals-style signals guiding many audits.
Finally, you will see how to reconcile conflicting results across tools, devices, and locations. If you want a calmer, more accurate process, this guide gives you one.
Contents
- 1 What “website speed” really means in the browser and for real people
- 2 How perceived speed differs from technical speed and why that changes your priorities
- 3 The metrics that matter most when you want to improve website speed
- 4 How to measure website speed with repeatable, apples-to-apples tests
- 5 Use a triage decision path to find the real bottleneck without guesswork
- 6 Common speed pitfalls and misconceptions that keep sites slow
- 7 Comparing performance improvement approaches: assets, code, infrastructure, and third parties
- 8 When speed work gets tricky: single-page apps, dynamic pages, and real-world variance
- 9 Frequently asked questions about understanding website speed
- 9.1 What is the difference between page load time and perceived website speed?
- 9.2 How often should I test website speed after updates?
- 9.3 Why do my speed test results vary between tools and locations?
- 9.4 What is the best starting point if my homepage is fast but product pages are slow?
- 9.5 Can compressing images hurt quality or accessibility, and how should I choose settings?
- 9.6 How do third-party scripts affect website speed, and what should I do about them?
- 9.7 What should I check when my site has good metrics but users still complain about slowness?
- 9.8 Is it worth optimizing for mobile first if most visitors use desktop?
- 9.9 How can I measure improvements in website speed without breaking SEO or functionality?
- 9.10 What should I do if my Core Web Vitals-style scores improve but conversions don’t?
- 10 Bring it together: a practical cycle to improve website speed and keep it improved
What “website speed” really means in the browser and for real people
Website speed is not only “time to first byte” from your server. It is the whole journey from navigation to the moment users can read, interact, and trust what they . A page can respond quickly yet still feel slow if rendering is delayed or the interface locks up.
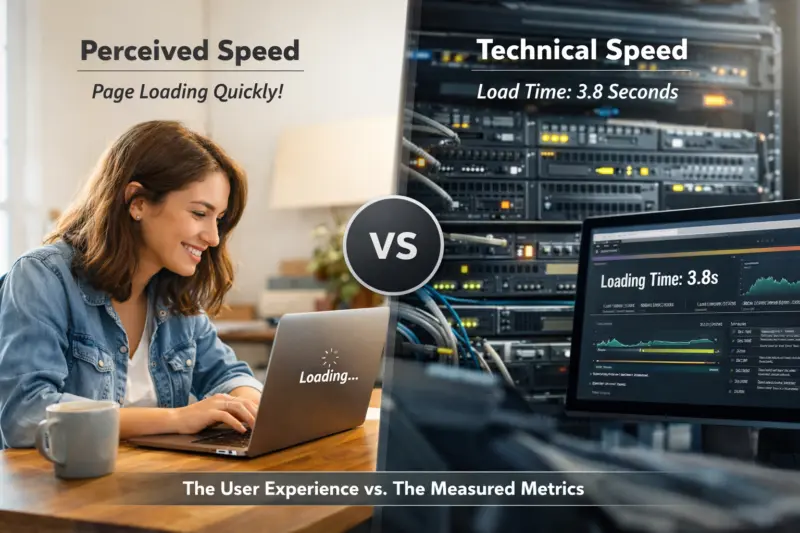
This is where perceived speed matters. Users judge how fast content appears and whether controls work promptly. Meanwhile, your technical timings track server response and how quickly assets load. Both views are important, but perceived speed often drives satisfaction and behavior.
Also, “page load” alone is incomplete. Pages can show the initial view early, but still take longer to become interactive. They can display content that later shifts, which feels like slowness. Therefore, speed must include rendering progress, user readiness, and visual stability.
A common nuance is that fast initial load can still feel bad. For example, late font loading can cause text reflow. Images that reserve the wrong space can push content down. As a result, the page may look broken for a moment, even if the first paint was quick.
Device class adds another layer. Low-end Android phones handle JavaScript and decoding differently than desktop computers. So “fast” on one device may be average on another. Tool results should be checked across representative devices, not only your test laptop.
How perceived speed differs from technical speed and why that changes your priorities
Perceived speed is the experience a user feels, while technical speed is the timeline your tools record. If you chase only server metrics, you may miss the real cause. For most modern sites, the browser’s work often dominates how slow it feels.
Technical speed includes network transfer, server response, and caching behavior. It also includes how quickly critical resources download and execute. Perceived speed includes how quickly meaningful content becomes visible. It also includes whether buttons respond without delay.
In practice, these can diverge. For instance, a server can be fast, yet a page can still wait on a heavy JavaScript bundle. Meanwhile, the browser might be busy with long tasks, which blocks interaction. Therefore, your priority should match what users actually feel.
You can connect the two by mapping “when users should care” to your metrics. When does the main headline appear? When can the user scroll smoothly? When do form fields become responsive? When does layout stop shifting?
A frequent misconception is that improving server response automatically improves perceived speed. It can, but it depends on what else is happening. If rendering is blocked by render-blocking scripts or CSS, server wins may be wasted. Edge cases include pages that appear stable but block interaction for a few seconds due to hydration work.
To ground your approach, align with established browser performance guidance such as web.dev and the Google Search Central documentation for performance signals in search contexts. These sources emphasize user-centric metrics, not just raw timing.
The metrics that matter most when you want to improve website speed
Good metrics help you target fixes that reduce user friction. For most teams, this means combining responsiveness, visual completion, and stability signals. When you pick indicators that reflect user outcomes, your work becomes easier to prioritize.
Responsiveness metrics reflect how quickly the page responds to user input. Visual completion metrics reflect when the main content is actually on screen. Stability metrics reflect how much the page layout shifts while loading, which users feel as “jumpy.” Together, these help you decide whether to focus on rendering, assets, or interaction delays.
In real audits, heavy JavaScript often shows up as sluggish responsiveness. Render-blocking CSS can delay visual completion. Oversized images can bloat load time and delay decoding. Third-party scripts can add both network and main-thread work. Slow backends can still matter, especially on cache-missed navigations.
When a metric looks bad, you should interpret it as a pattern, not a verdict. For example, poor responsiveness often points to long tasks on the main thread. Poor visual completion often points to delayed content rendering. High visual instability often points to missing dimensions or late-loading fonts and images.
Tools can disagree, so reconcile them with repeat testing. One tool might run without the same caching state or device assumptions. Another tool might not capture the moment a user starts interacting. Therefore, confirm with multiple views, then test on devices that resemble your users.
How to measure website speed with repeatable, apples-to-apples tests
To measure website speed correctly, start with a baseline and then retest under controlled conditions. Do not rely on a single run or a single tool. Instead, repeat tests and compare ranges, not one lucky number.
A reliable workflow is simple. First, capture a baseline for a few representative pages. Next, identify the biggest contributors in the waterfall. Then, apply one change at a time and retest the same pages.
Separate lab data from field data. Lab tools use consistent throttling so you can compare results. Field data captures what real users experience, including varied networks. If you only use one type, you can miss edge cases.
Also control cache state. A warm cache run can hide problems that appear on first visits. A cold run can exaggerate issues that might be rare. Testing both can reveal whether the bottleneck is reuse of cached assets or first-load behavior.
When collecting evidence, use request breakdowns and warnings. Waterfall views help you see which resources block rendering. Console and network logs can reveal failed requests, mixed content, or blocked scripts. Finally, confirm with error monitoring to avoid optimizing a page state that only fails for some users.
Personalization and dynamic content can make “average” results misleading. For example, logged-in users might load different scripts. A/B variants can also shift resources and timings. Therefore, measure the exact templates your users hit, not only the marketing page everyone benchmarks.
Use a triage decision path to find the real bottleneck without guesswork
A decision path helps you stop random optimizations and focus on what is actually slow. Start by identifying which stage feels broken. Network delays, code execution, rendering, media size, and third-party overhead each leave different clues.
First, compare timelines. If the main content appears late, rendering or critical resources might be delayed. If interaction feels delayed, JavaScript execution and main-thread work likely matter. If the page loads but shifts visually, layout stability is probably the culprit.
Then prioritize fixes using a simple framework. Consider user impact first. Next, estimate effort and ownership. Finally, check regression risk, especially when changing caching or script loading.
Here is how to branch mentally. If visuals show up late, review critical CSS and JavaScript execution order. If visuals shift, fix dimensions, font behavior, and late media insertion. If requests balloon, audit third-party tags and bundle strategies.
Also match fixes to page type. A blog article might bottleneck on images and typography delivery. A landing page might bottleneck on tracking and marketing scripts. A dashboard app might bottleneck on long tasks and route transitions.
A key limitation is “optimizing the wrong thing.” For instance, minifying assets may not help if the dominant cost is long-running client scripts. Likewise, adding a CDN may not fix slow main-thread work. Therefore, triage first, then optimize.
Common speed pitfalls and misconceptions that keep sites slow
Many teams assume only server response time determines speed. However, modern pages often feel slow because of front-end work, not back-end speed. Browsers must download assets, parse code, execute scripts, and render pixels. If that work is heavy, perceived speed suffers.
Typical pitfalls include too many third-party tags and uncontrolled script growth. Oversized images and unoptimized video thumbnails also slow things down. Blocking JavaScript can delay rendering and keep users staring at a blank state. Inefficient caching can force repeated downloads that should be reused.
Minification can help, but it is not a cure-all. Over-minifying can reduce debuggability and complicate maintenance. It can also limit caching granularity if everything changes together. Therefore, prioritize structural improvements first, then apply smaller wins.
Layout instability and font handling are frequent culprits. If fonts load after content is laid out, text can jump. If images lack consistent sizing, elements can push down. Users interpret these shifts as slowness, even when network times look fine.
Another subtle pitfall is measurement contamination. Bot protection can alter responses. Geo routing can change which edge server serves assets. Service worker caches can change behavior after a user has visited once. Meanwhile, background sync and personalization can make one test look fine and another look broken.
Comparing performance improvement approaches: assets, code, infrastructure, and third parties
Different performance problems need different solution categories. Asset optimization focuses on what you deliver. Code execution focuses on what the browser does. Infrastructure focuses on where and how it is served. Third-party governance focuses on vendor-added overhead you did not author.
Asset optimization and delivery usually targets images, fonts, and bundle structure. For images, modern formats and responsive sizing can reduce bytes. Compression and proper dimensions reduce decoding time. Bundling strategies can prevent shipping unused code to every visitor.
Code execution and rendering improvements reduce main-thread work. Splitting bundles helps load less code upfront. Deferring non-critical scripts can let users see content sooner. Removing render blockers can move the first meaningful paint earlier.
Infrastructure and distribution improvements target latency and reuse. CDN placement can reduce round trips. Connection reuse can reduce handshake costs. Server-side caching and database tuning can improve cache-missed navigations. However, infrastructure gains are most valuable when network or origin latency is the dominant bottleneck.
Third-party governance is often the hidden variable. Tag consolidation can reduce duplicate work. Loading strategies can ensure non-essential tags start after the page is usable. Performance budgets help prevent new scripts from eroding gains over time.
A helpful rule is ownership. Some fixes only work if you control the code. Otherwise, you mitigate via loading strategy, configuration, or vendor changes. This ownership-aware approach avoids frustration and wasted effort.
| Improvement category | Typical symptoms | What to verify next |
|---|---|---|
| Asset optimization & delivery | Large images, slow decoding, delayed main visuals | Image formats, responsive sizes, font strategy, request sizes |
| Code execution & rendering | Main-thread stalls, delayed interaction readiness | Script execution order, bundle splitting, render blockers |
| Infrastructure & distribution | High latency on first loads, slow cache misses | Edge/CDN behavior, cache headers, origin timing |
| Third-party governance | Tag bloat, long tasks from vendors, unpredictable waits | Tag audit, load timing, error rates, performance budgets |
When speed work gets tricky: single-page apps, dynamic pages, and real-world variance
Single-page apps and dynamic sites can change what “fast” means. Route transitions often feel separate from the initial page load. Users may judge speed by how quickly the next view appears and becomes interactive.
In a single-page app, client rendering and hydration affect responsiveness. Initial HTML may look fine, but long tasks can delay interaction. Meanwhile, route transitions may load additional code on demand, causing unpredictable delays. Therefore, measure key routes, not only the landing screen.
Dynamic content adds complexity. Authenticated pages can load different scripts and data. Personalization can change which assets appear, which can break caching assumptions. If your cache policy is optimized for public pages, logged-in users may still have slow first loads.
Edge cases also appear in the network layer. Intermittent DNS or TLS resolution can create slow navigations that vanish later. Geographic differences can change which edge server serves assets. Finally, browser differences can affect decoding, JavaScript execution, and rendering behavior.
A common mistake is to assume that one improvement will stay stable. As content grows, templates change, and new scripts get added, performance budgets can erode. Therefore, treat speed as an ongoing system, not a one-time project.
For modern performance guidance, reference web.dev when you plan metric targets and interpret user-centric signals. Pair that with monitoring in your analytics or monitoring stack so you see real user impact.
Frequently asked questions about understanding website speed
What is the difference between page load time and perceived website speed?
Page load time is a technical milestone, like when the page finishes loading resources. Perceived website speed is how fast users feel the page becomes usable. If interaction is blocked by long tasks, users will feel slow even if load time looks decent.
How often should I test website speed after updates?
Test after any major release, especially when you change templates, scripts, or caching rules. Also test before and after big traffic events, because load patterns can change. For ongoing quality, run a monthly or biweekly performance check and alert on regressions.
Why do my speed test results vary between tools and locations?
Different tools use different throttling, caching states, and browser versions. Locations matter because network routing and edge cache hit rates change by geography. As a result, you may see different timelines even for the same URL.
What is the best starting point if my homepage is fast but product pages are slow?
Start by comparing product page templates to the homepage. Product pages often load different scripts, tracking tags, and image sets. Then compare waterfalls to find which requests and code execution differ most.
Can compressing images hurt quality or accessibility, and how should I choose settings?
Yes, aggressive compression can reduce visual quality, especially on text-heavy images. It can also harm usability if it causes banding or blurring. Choose settings based on a visual check, keep proper alt text, and test on multiple screen sizes.
How do third-party scripts affect website speed, and what should I do about them?
Third-party scripts can add network requests, run code on the main thread, and delay rendering or interaction. They can also fail in ways that create extra retries. Audit tags, load them only when needed, and measure impact with controlled tests.
What should I check when my site has good metrics but users still complain about slowness?
Check real user traces for slow sessions that lab tests do not reproduce. Focus on interaction delays, long tasks, and layout shifts, not only initial paints. Also review device mix and geography, since some users may hit slow routes and cache misses.
Is it worth optimizing for mobile first if most visitors use desktop?
Often, yes, because mobile bottlenecks differ and mobile traffic can grow quickly. Even for desktop-heavy audiences, third-party tags and main-thread work still affect responsiveness. By fixing shared bottlenecks, you can improve both mobile and desktop experiences.
How can I measure improvements in website speed without breaking SEO or functionality?
Use a staging environment and verify that rendering changes still match the intended output. Then release behind feature flags or a controlled rollout where possible. Monitor errors, conversions, and crawl-related issues after deployment.
What should I do if my Core Web Vitals-style scores improve but conversions don’t?
Performance can improve, yet conversion depends on more than speed alone. Re-check funnel steps, form friction, pricing clarity, and content relevance. Then validate that the same user journeys improved, not only the benchmark page.
Bring it together: a practical cycle to improve website speed and keep it improved
Website speed work becomes manageable when you follow a repeatable loop. First, measure a baseline across representative pages and devices. Next, interpret the signals to identify bottlenecks that match user experience, not just tool readings.
Then prioritize fixes by user impact and ownership. After each change, run controlled re-tests and compare ranges, not single numbers. Finally, monitor for regressions as new features, content, and third-party tags get added.
The most reliable teams also set performance budgets tied to their site type. Content sites can focus on media delivery and typography behavior. Commerce pages can focus on product template scripts and image sets. App-like dashboards can focus on long tasks and route transitions.
If you need a next step, choose one bottleneck category to address first. Run controlled tests, then document what you changed and what improved. Over time, this builds internal speed literacy, so future releases avoid silent performance erosion.
If your team lacks bandwidth, you can consider working with a performance specialist to run a professional audit. Still, the best results come when you combine expert analysis with your own repeat testing routine.
Updated September 2026