If you want better user experience, don’t guess from “site speed” alone. Instead, use Website Performance Metrics for User Experience to predict where users feel friction, then validate those signals with real-user evidence. This guide walks you through the essential metrics, how to measure them, and how to turn results into prioritized improvements in 2026, when lab and field data often diverge.
You will learn what to track across journeys, how to interpret percentiles and segments, and how to separate diagnosis from proof. You will also get a release workflow for catching regressions early, plus a clear way to set thresholds that match user behavior rather than vanity targets.
Contents
- 1 Choose UX-focused metrics by mapping them to real user journeys
- 2 Use user-impact signals that go beyond Core Web Vitals-style indicators
- 3 Measure UX performance with field data, lab data, and synthetic checks together
- 4 Connect loading, interactivity, and visual experience metrics to specific failure modes
- 5 Set thresholds and priorities from UX impact, not from generic pass-fail rules
- 6 Avoid misconceptions that make UX performance conclusions misleading
- 7 Select the right measurement approach based on your website type and maturity
- 8 Diagnose performance regressions with a release-safe workflow for UX
- 9 Interpret UX performance by region and device so metrics remain comparable
- 10 Frequently asked questions about essential website performance metrics for user experience
- 10.1 Which website performance metrics matter most for user experience?
- 10.2 How do I interpret performance metrics when field and lab results disagree?
- 10.3 What metrics should I track for mobile users specifically?
- 10.4 How can I tell whether a metric problem is caused by third-party scripts?
- 10.5 Are Core Web Vitals enough to measure website performance for user experience?
- 10.6 What’s the difference between user experience timing and technical page load metrics?
- 10.7 How often should I review Website Performance Metrics for User Experience in 2026?
- 10.8 How do I set realistic thresholds without comparing apples to oranges?
- 10.9 Why do percentiles matter more than averages for UX metrics?
- 10.10 How can I prevent measurement errors like bot traffic or caching from skewing my results?
- 11 Turn UX performance metrics into measurable improvements you can sustain
Choose UX-focused metrics by mapping them to real user journeys
Good website performance metrics measure what users feel during tasks, not just what browsers log. Start by mapping journeys like home → product → cart → checkout, then attach metrics to each step users experience. This is how performance becomes an experience outcome, such as fewer abandoned forms or smoother product browsing.
website speed is only one piece of UX. Users also notice delays before content becomes useful, sudden visual changes, and confusing moments when actions do nothing. Therefore, UX-focused metrics should cover perceived responsiveness, visual stability, task completion friction, and error or abandonment signals.
To make this practical, translate journeys into page types and user intents. A blog post demands reading comfort and quick above-the-fold rendering. A checkout page demands fast interactivity and stable layout to avoid misclicks. A search page demands quick results readiness and reliable keyboard and screen-reader behavior.
Next, segment your evidence so you learn where pain happens. Compare new vs returning users, mobile vs desktop, and logged-in vs anonymous sessions. You will often find that one cohort experiences the worst friction even if averages look fine.
Finally, connect metrics to success events. If users abandon when a form is “almost ready,” that points to readiness timing and visual stability issues. If they abandon after repeated errors, focus on error rates, retry success, and input responsiveness under stress. A common mistake is watching page-level metrics while ignoring the journey step that users actually struggle with.
Use user-impact signals that go beyond Core Web Vitals-style indicators
Core Web Vitals-style metrics are a strong foundation for UX, but they do not cover every experience failure. Use them to anchor the “how fast and stable” story, then add broader outcome signals that capture task success and confusion. This combination helps you explain user satisfaction outcomes, not only technical behavior.
For example, visual stability indicators help explain layout shift complaints. However, a user might still feel stuck even when visuals are stable. That can happen when controls respond late, when “loading” overlays block input, or when third-party scripts delay key interactions. By pairing stability signals with interaction readiness and task metrics, you gain a fuller UX picture.
In addition, UX differs by page purpose. A landing page with heavy marketing assets may need different weighting than a support article that values fast readability. Therefore, define metric priorities per page type and per step in your journey. Otherwise, you may optimize a metric that matters less than another for that page’s user goal.
Practical mapping looks like this. If your product list feels slow, track content readiness timing and interactivity readiness for list filters. If your search experience feels frustrating, track time to results and error recovery when queries fail. If your checkout feels risky, track input responsiveness and visual stability around price, shipping, and payment fields.
One nuance is distribution. A metric might pass in a lab run and still hurt a small segment in the field. That segment might be users on weaker devices or slower networks, or users behind specific CDN paths. Always interpret results with percentiles and segments so you see the UX harm that averages hide.
Measure UX performance with field data, lab data, and synthetic checks together
Use field data to answer “what happens for real users,” and lab data to answer “why it happens.” Synthetic checks then help you detect regressions and coverage gaps across pages. When you use all three, you can diagnose root causes without relying on guesses.
Field measurement comes from real-user monitoring, or RUM, which captures performance from actual browsers. Lab measurement uses controlled tests that mimic user conditions, usually with repeatable scripts. Synthetic monitoring runs automated checks on a schedule across key pages, often from multiple regions.
Each method serves a distinct purpose. Field data is your truth because it includes real networks, device diversity, and real traffic patterns. Lab data is your diagnostic microscope because you can reproduce and isolate changes. Synthetic checks are your early warning system, especially for third-party drift, broken experiments, or configuration issues.
However, measurement bias is real. Sampling can undercount certain user types. Traffic mix shifts after campaigns can change percentiles. Ad blockers, service workers, and cache behavior can also change the meaning of a metric. Meanwhile, bot traffic can pollute measurements if it is not filtered.
To trust trends, validate the trend quality before acting. Use stable release windows, ensure instrumentation is complete, and verify enough samples per segment. Also, treat sudden changes after a deploy as suspicious until you confirm they are statistically meaningful. A common mistake is reacting to one-day anomalies without checking release state and traffic mix.
For strong UX measurement practices, see Web Vitals report and guidance from Google Chrome UX Report as starting points.
Connect loading, interactivity, and visual experience metrics to specific failure modes
Users experience performance in phases, so map metrics to what happens next on the screen. That helps you connect long delays to the right failure mode. Then you can fix the cause instead of chasing the wrong symptom.
In practice, think in phases like initial rendering, content readiness, interactivity readiness, and visual progression. A user might see a blank area while the app boots, or content might appear but controls may not respond. Layout changes can also shift elements after users start reading, which leads to mis-taps and distrust.
Different metrics point to different problems. If interaction readiness is late, heavy JavaScript execution or blocked main-thread time is often involved. If content readiness is late, network dependency order and server response delays may be the issue. If stability signals worsen, image sizing, font loading, or late-loaded UI components can be the culprit.
One tradeoff you will face is optimization side effects. For example, reducing one asset can improve interactivity, while changing rendering behavior can increase layout shifts. Therefore, treat improvements as hypotheses. Measure before and after with consistent conditions so you confirm the UX outcome, not just the metric delta.
Edge cases matter too. In single-page applications, route changes can shift metric behavior, especially when navigation reuses the same shell. Track at the route level, not only at the initial page view. Otherwise, you might “fix” the home page while users still struggle on a key route like account settings.
When a metric regresses, use a diagnostic workflow. First, identify the UX phase that changed. Next, check segmentation to find the affected devices and user cohorts. Finally, use lab reproduction to test the suspected cause before rolling out a broad change.
Set thresholds and priorities from UX impact, not from generic pass-fail rules
To improve user satisfaction, set thresholds that reflect UX harm and business risk. Avoid using one-size pass-fail targets because your users and page types differ. Instead, start from observed distributions, then define action thresholds by impact and controllability.
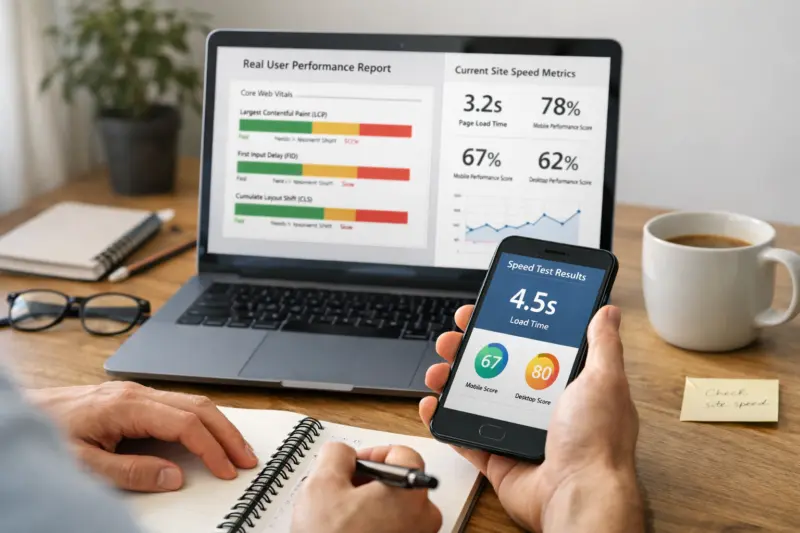
Begin with the worst segments. Look at percentiles like 75th and 95th, not only the median. A small tail of slow experiences can drive many complaints and abandonments. Therefore, prioritize what hurts the most users most often, even if averages look acceptable.
Then incorporate business context. A slightly slower blog may be tolerable, but a delayed checkout step can reduce revenue quickly. A stable cart layout matters more during payment entry than during article browsing. As a result, define page-type weightings so you do not optimize the wrong part of the funnel.
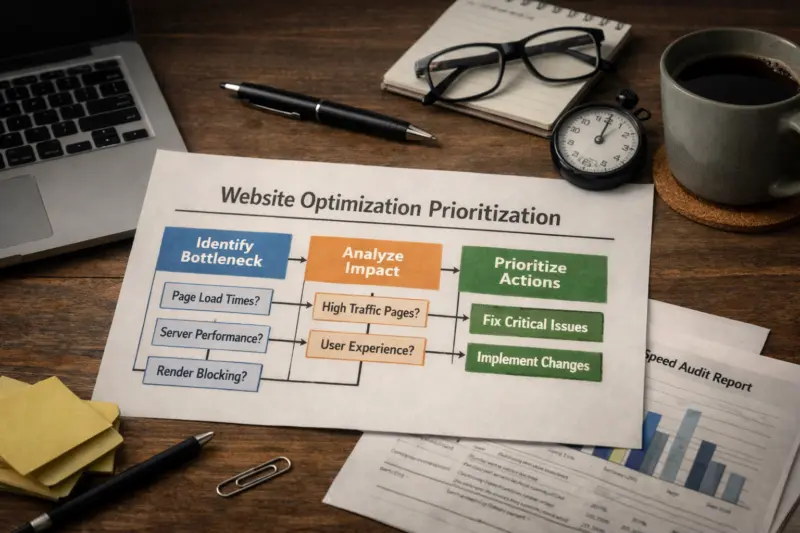
Next, rank fixes using severity, frequency, confidence, and effort. Severity measures how badly users feel the problem. Frequency measures how often it affects sessions. Confidence reflects how clear your evidence is, based on field data and reproduction. Effort is the engineering and release cost required to change the root cause.
Real-world nuance is that thresholds should evolve with your release cadence. After redesigns or major migrations, the distribution can shift. That means yesterday’s “good” can become today’s baseline. In 2026, many teams also run more experiments, so you should adjust thresholds per experiment cohort to avoid misleading conclusions.
A common mistake is comparing thresholds across unrelated page groups. Comparing a product listing with a support article ignores different rendering patterns and user intent. Keep thresholds within comparable groups, and review them after major content or UI changes.
Avoid misconceptions that make UX performance conclusions misleading
Several common beliefs lead teams to the wrong UX conclusions. The biggest one is assuming lab tests alone guarantee real user experience. Another is treating mobile and desktop as interchangeable. A third is believing one metric summarizes everything.
Lab tests are useful, but they can miss real variability. Real networks fluctuate, devices differ in CPU and memory, and third-party scripts can load unpredictably. Additionally, caches and CDNs may change behavior, depending on region and prior visits. Therefore, lab success without field confirmation can give false confidence.
Mobile differs for reasons beyond speed. Device capability affects script execution, image decoding, and input event timing. Network variability changes resource waterfall patterns. Even fonts and rendering engines can produce different visual stability behavior. For that reason, segment by device classes and network conditions rather than using one “mobile” label.
Also, beware of instrument and data mixing. Bot traffic can inflate performance by avoiding heavy assets. Tagging gaps can make metrics look better than reality. Missing route context can hide that only one navigation path regressed. Caching inconsistencies can cause synthetic checks to disagree with RUM.
Deeper insight comes from reconciliation. When field and lab results disagree, look for differences in cache state, service worker behavior, and third-party execution timing. Then reproduce the exact segment conditions in a lab environment. If you cannot reproduce, investigate instrumentation and sampling first.
Red flags include sudden “improvements” that only appear in one region, or stability gains that coincide with missing user events. When those show up, treat the metric story as incomplete until validated.
Select the right measurement approach based on your website type and maturity
Pick measurement methods based on the UX questions you need answered, and the resources you have to keep them accurate. You can start lightweight, but you need a clear path to richer insight as your website evolves. The goal is coverage and diagnostic value, not dashboard quantity.
Browser-based user-experience reporting captures performance from actual browsers, often via JavaScript instrumentation. RUM focuses on real users and includes field variability. Synthetic monitoring provides consistent coverage across key pages and detects regressions quickly. Application-layer beacons add granularity, such as route-level readiness and interaction-level timing.
If you run a content site, you may prioritize readability timing and visual stability around hero media. If you run eCommerce, you also need cart and checkout responsiveness, form error recovery, and reliable navigation timing for filters. If you run a SaaS marketing site, you may prioritize lead capture readiness and stable modal interactions. For authenticated apps, route-level tracking and component-level events become essential.
Tradeoffs exist in every stack. Lightweight setups are cheaper but may miss interaction timing or route context. Deep observability reduces guesswork but increases operational overhead and requires careful event taxonomy. Additionally, tools differ in aggregation, sampling, and timing definitions, so you must interpret outputs as “method-dependent.”
To avoid losing longitudinal comparability, standardize definitions and keep release measurement consistent. When you add new events, version your instrumentation so historical comparisons stay meaningful. Meanwhile, do not overfit to one tool’s percentile math. Validate with field evidence and sanity-check with reproduction.
If you want official background on how Web Vitals are reported, review Web Vitals report and practical measurement notes from Chrome UX Report.
Here is a comparison you can use as a decision aid, especially when building your measurement stack in 2026.
| Approach | Best for | Limitations to plan for | When to choose |
|---|---|---|---|
| RUM (field) | Truth about what users experience by segment | Sampling bias and instrumentation gaps can mislead | Ongoing UX monitoring and “where it hurts” analysis |
| Lab testing | Reproduction and diagnosis under controlled conditions | May miss real variability like cache state and network jitter | When regressions appear and you need root causes |
| Synthetic monitoring | Regression detection and coverage across pages | Checks can pass while real users still struggle | When you need early alerts before users complain |
| App events and beacons | Route-level timing, interaction readiness, and error recovery | Higher setup effort and event taxonomy drift risk | Authenticated apps and complex journeys with many steps |
Diagnose performance regressions with a release-safe workflow for UX
Regressions can ruin user experience before you even notice. A release-safe workflow helps you catch changes quickly and isolate likely causes. It also prevents you from blaming code when the real issue is configuration or third-party drift.
Start with baselines before each deploy. Capture field distributions and key journey metrics for the days leading up to the release. Then compare post-deploy distributions using the same segments. Focus on tails and worst segments, not only overall medians.
Next, use lab tests to localize causes. Reproduce the exact route and conditions that show the regression. If stability got worse, inspect layout-affecting changes like fonts, image sizing, and component mounting. If interactivity regressed, inspect main-thread work and dependency shifts.
Then isolate what type of change likely caused the regression. Code changes point to JavaScript execution or rendering logic. Configuration changes point to CDN behavior, caching headers, or compression differences. Content changes point to asset size and dependency order. Third-party drift often shows up as new failures around consent, analytics, or widgets.
Deeper insight comes from confounders. Traffic mix changes can mimic performance regressions. Cache warming differences after a deploy can change observed timing for a few hours. Marketing campaigns can shift user device and region distributions. Seasonality can also alter network patterns and user behavior.
To build confidence before declaring causality, require “good evidence.” That means the regression aligns with the deploy window, appears in field distributions, and can be reproduced in lab. Also define rollback criteria early, such as when a key journey percentile crosses a severity threshold for multiple days.
Interpret UX performance by region and device so metrics remain comparable
Segment your UX metrics by device and region to interpret them correctly. Otherwise, you may optimize issues that mostly come from network distance or weaker hardware. In turn, that can waste effort and delay fixes that matter for the biggest user groups.
Device capability influences script execution, rendering cost, and interaction readiness. Entry-level Android devices can behave very differently from modern iPhones or desktops. Therefore, group devices into practical capability bands, such as low-, mid-, and high-tier. Then apply thresholds per band so you avoid comparing apples to oranges.
Region matters because CDN edge proximity changes resource timing. It also changes how quickly third-party scripts load and how stable connections remain under load. As a result, interpret metric distributions by region without overfitting to one location’s network characteristics. If one region is consistently worse, you can decide whether to prioritize CDN configuration, asset compression, or route-specific changes.
Language and layout can also change UX behavior. For example, right-to-left layouts, translated strings, and font sets can affect visual stability. That can shift layout shift signals around headers, navigation, or form labels. Therefore, segment by language and check stability around UI elements that reflow.
When you prioritize segments, use both impact and proportion. A small region with severe issues may not deserve top priority over a larger segment with moderate issues. Meanwhile, if that region drives key revenue, such as enterprise signups, treat it as high priority even if the sample is smaller.
A common mistake is “fixing the code” when the issue is actually a cache path, browser version mix, or third-party configuration by region. Always confirm the segment root cause before large rollouts.
Frequently asked questions about essential website performance metrics for user experience
Which website performance metrics matter most for user experience?
The most useful metrics follow the user journey. Track perceived responsiveness and interactivity readiness on key steps, plus visual stability where layout changes can cause misclicks. Also include task success signals like form completion, search success, and error recovery, because one timing metric rarely explains all UX outcomes.
How do I interpret performance metrics when field and lab results disagree?
Start by comparing the same segment conditions: device class, network, route, and cache state. Then check whether sampling or tagging differences could explain the gap. If you can reproduce the issue in lab for that route, it supports a diagnosis; if you cannot, focus on instrumentation and third-party execution differences first.
What metrics should I track for mobile users specifically?
Track interaction readiness and responsiveness on mobile controls, plus visual stability around images and fonts. Segment by device capability and network variability, since tails can affect real usability even when averages look fine. Also monitor input and error events for mobile forms, because user frustration often shows up as retries and abandonment.
How can I tell whether a metric problem is caused by third-party scripts?
Look for regression timing that aligns with third-party deployment changes or consent-related loading paths. Then isolate the route where the issue appears and test with and without the third-party under controlled conditions. Finally, confirm with field segmentation, since third-party execution can differ by region, browser, and user state.
Are Core Web Vitals enough to measure website performance for user experience?
Core Web Vitals provide key UX signals for loading, interactivity, and visual stability. However, they miss some journey-specific failures like form error recovery, search result readiness, and task completion friction. Add UX-outcome metrics to connect technical performance to satisfaction and conversion behavior.
What’s the difference between user experience timing and technical page load metrics?
User experience timing focuses on when the user can actually do something and see meaningful content. Technical page load metrics often describe what the browser completed, which can happen before the UI feels usable. Because modern web apps use progressive rendering and client-side routing, the two views can diverge.
How often should I review Website Performance Metrics for User Experience in 2026?
Review UX performance continuously with alerts, then do deeper weekly or biweekly reviews. Increase scrutiny around major releases, migrations, and marketing campaigns, since traffic mix and behavior can change quickly. Also run post-deploy validation windows to confirm fixes with field evidence.
How do I set realistic thresholds without comparing apples to oranges?
Use comparable page groups and segment by device and region before setting thresholds. Then base targets on observed distributions, especially percentiles that represent real user pain. If page types differ in intent, set separate targets per page category so optimization matches the journey.
Why do percentiles matter more than averages for UX metrics?
Percentiles show the spread of user experience, including long tails that drive real complaints. Averages can hide that a small but meaningful portion of users has very slow or unstable experiences. For UX improvement, target the percentiles where harm begins, often 75th and 95th.
How can I prevent measurement errors like bot traffic or caching from skewing my results?
Use bot filtering and validate that tagging fires consistently across routes and states. For caching, ensure tests and RUM interpretation consider cache hit rates and CDN paths. Then sanity-check by comparing synthetic runs against field segments, and confirm that the regression pattern matches what you see in user behavior.
Turn UX performance metrics into measurable improvements you can sustain
After you define the right metrics, improvements should become repeatable, not one-off wins. Keep your measurement tied to user impact and use field evidence as the final proof. When you do that, you avoid optimizing for dashboards that do not change what users feel.
Use a decision path that starts with user-impact metrics and ends with post-deploy validation. First, pick one or two critical journeys where users feel friction. Next, validate the signals with tooling and lab reproduction to identify likely causes. Then prioritize fixes by expected UX improvement per effort.
Finally, sustain the gains with monitoring around releases and experiments. Watch key percentiles and the worst affected segments, and confirm that improvements persist across device and region groups. If you maintain this loop, your team builds a reliable system for learning, diagnosing, and improving.
If you are starting today, choose one journey such as search-to-results or cart-to-checkout. Establish baselines for field distributions, then set thresholds that reflect user harm. After your first optimization, validate with post-deploy evidence and compare the tails, not only the averages.
Updated September 2026