Schema markup is a way to describe your page content to search engines using structured data, and “types” means choosing the right schema categories and fields for what each page truly represents. When learning types of schema markup for SEO, you’re really learning which schema types match each page’s intent and entity. For webmasters and SEO pros, the payoff is clearer interpretation by crawlers and a better chance at eligible structured results. The wrong type can waste engineering effort or create validation problems, even if the code looks correct.
In 2026, the core idea is still simple: choose schema types that reflect the actual, visible content on the URL. You also need an implementation approach that stays truthful as your templates and data change. This guide focuses on how schema “types” map to real pages, how to choose them without guesswork, and how to avoid common pitfalls that block value. It avoids a full spec dump and instead gives you a decision framework you can apply to your site.
You’ll map schema type families to common scenarios like Organization, LocalBusiness, Person, Article, and commerce-related pages. You’ll also learn how different serialization formats affect maintainability, and why correctness beats volume. Finally, you’ll work through tricky edge cases like multi-entity pages and frequently changing data. Along the way, you’ll see what to validate, what errors usually mean, and how to iterate safely.
Contents
- 1 How schema “types” translate into what search engines understand
- 2 How to choose the right schema type family for each page goal
- 3 Core schema types you’ll use for common professional site pages
- 4 How structured-data formats relate to schema types and maintainability
- 5 Common mistakes that prevent schema types from helping SEO
- 6 Edge cases where choosing schema types gets tricky
- 7 Building a maintainable schema system across your site architecture
- 8 Frequently asked questions about understanding types of schema markup for SEO
- 8.1 What are the main types of schema markup, and how do I choose between them?
- 8.2 How do schema types differ from schema properties when planning implementation?
- 8.3 Should every page on my site include schema markup, or only specific page types?
- 8.4 What happens if the schema markup doesn’t exactly match the visible content?
- 8.5 Can I use multiple schema types on the same URL without confusing search engines?
- 8.6 How do I validate that my schema implementation is correct in 2026 workflows?
- 8.7 What’s the difference between Organization and LocalBusiness schema types for SEO purposes?
- 8.8 When should an SEO team prefer JSON-LD over other schema implementation formats?
- 8.9 How can we prevent schema drift when CMS templates or content templates change?
- 8.10 How do schema types work for content like FAQs, guides, or help-center articles?
- 9 Conclusion: schema types are a modeling decision, not a one-time checklist
How schema “types” translate into what search engines understand
Schema types tell search engines what kind of real-world entity or content your page is about. In practice, the type you choose becomes the anchor for meaning, eligibility, and the fields you should provide. That is why schema types of markup matters for SEO: it shapes the interpretation of your content.
Most confusion comes from mixing up “type” and “properties.” A schema type is the category, like Organization or Article, and properties are the details you attach, like name, author, or publication date. When you pick an incorrect type, you often end up adding fields that do not describe the same entity the page presents. Search engines can still parse the JSON-LD, but the entity interpretation may fail or become unreliable.
Search engines use structured data to connect entities across pages. If your site consistently identifies the same Organization with the same name and identifiers, crawlers can link pages to a known brand. If your author pages use a consistent Person schema, authorship signals become more coherent. This is not magic ranking, but it improves clarity, especially when pages are complex or template-driven.
Here’s the practical “mapping” mindset. First, identify your page’s primary subject and the entity that subject represents. Then choose a schema type family that matches that subject. Only after that do you decide which properties you can accurately supply, based on what is actually visible to users and available from your CMS.
A common misconception is that “more schema types” automatically creates more understanding. In reality, schema types are meant to be semantically coherent. If you combine types that do not match the visible page, you create ambiguity. A safer pattern is to select the single best main type and add secondary entities only when the page clearly supports them.
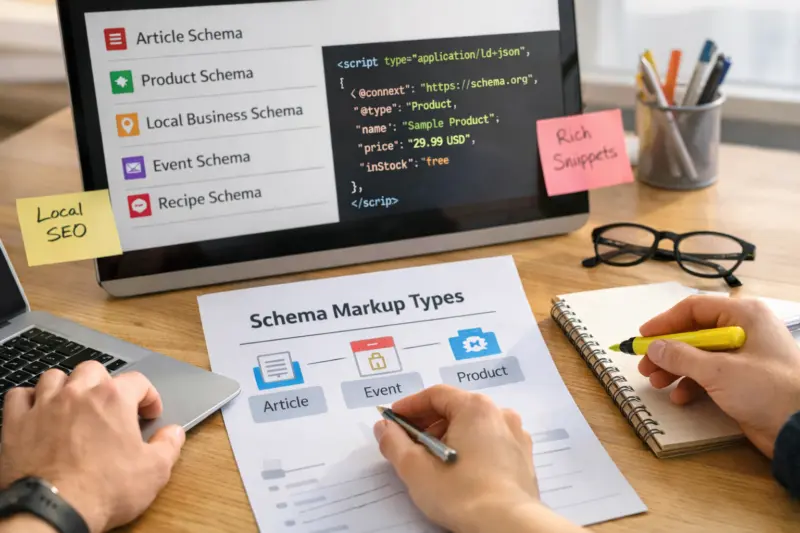
For background on how Google treats structured data, see Google Search Central – Structured data. For the underlying structured data format concepts, Schema.org – Introduction to Schema is a useful reference when you are validating ideas with real vocabularies. These sources do not replace testing, but they clarify expectations for how structured data is used.
How to choose the right schema type family for each page goal
Choosing the right schema type family starts with page intent and the main entity your URL is about. Once you identify that, you can pick the schema type that best matches the content you show on the page. This avoids the common mistake of forcing a template into a schema category it does not fit.
Use a step-by-step approach when planning your next template change. Identify the main subject users come for, like a specific service, a published article, or your company’s identity. Next, confirm the entity type you can truthfully support, such as Organization, LocalBusiness, Person, or Article. Then set a realistic goal for what you want structured data to do, like clearly labeling content or supporting eligible structured presentation.
Before you write any schema, check that the required fields you plan to include are genuinely present. For example, a Person type should not guess job titles or biographies you do not publish on the page. An Organization type needs a consistent name and brand signals that match visible site identity. If your CMS only shows partial data on some pages, you may need a broader type or a different page model.
Then think about your future maintainability. Schema types that require many properties can be fragile in dynamic setups. If your site often changes authors, updates editorial dates, or rotates staff for different locations, you need a schema model that can keep up. This is why “best match” often means “best match you can reliably maintain,” not the most specific type available.
Here’s an edge case you should plan for. A page may describe a service offered by an Organization and also include a featured staff member. The main type should remain aligned with the page’s primary subject, like a service-related page framed as a Service or a specific offering. You can add a secondary Person entity only if the page clearly identifies that person’s role and details. Keep the primary subject dominant so parsers do not receive conflicting context.
When schema type choices are made carefully, you avoid failure modes like schema contradicting visible content or creating inconsistent entity identities. A mismatch can still validate structurally but be ignored or underweighted in practice. This is especially relevant for multi-location brands where addresses and contact details must stay aligned with each canonical page.
Core schema types you’ll use for common professional site pages
Professional sites typically reuse a small set of schema type families that match their main page categories. The most common are Organization, LocalBusiness, Person, Article or BlogPosting, and commerce or service-related types when they truly apply. Understanding when each type fits helps you implement schema that stays truthful and useful.
Organization is a strong default for brand identity pages and company-about pages. It works when you can clearly provide the organization name, logo, and other brand signals that are consistent sitewide. A frequent overuse mistake is tagging every page as Organization when the page is really about a different entity, like an individual author or a specific location.
LocalBusiness is appropriate when you operate in a specific place and the page clearly describes that local entity. You should include accurate address, contact, service area details, and consistent location information when you use it. It is risky to use LocalBusiness on a general corporate page or on pages that do not represent a distinct local presence. If your site has separate location landing pages, LocalBusiness can be a better fit for those pages.
Person fits author bios, staff profiles, and editorial bylines when those pages publish identifiable author details. It becomes valuable when the person appears consistently across the site with the same name and profile URL logic. If you have guest authors whose details differ per article, you may need a separate author page model or an approach that avoids guessing.
Article or BlogPosting often fits editorial content, like guides and news-style pages. Use it when the page publishes a coherent, standalone article with a title, byline, and clear publication or update signals. A common mistake is applying Article schema to listing pages, category pages, or paginated archives that do not present a single article as the main content. For help-center or FAQ-style content, you may still use Article framing if it matches how users consume the content.
Tradeoffs show up when templates and partial data collide. If your CMS sometimes omits author details or hides them behind tabs, your structured data can become incomplete. Parsers may still read your markup, but missing essential context can limit outcomes. The goal is a minimum viable schema that is correct and evident, not a maximal schema that is inconsistent.
How structured-data formats relate to schema types and maintainability
The serialization format you pick does not change what the schema type means, but it changes how reliably you can maintain it. JSON-LD is usually the easiest to keep consistent across templates. Microdata and RDFa can work, but they often add coupling between markup and page layout.
In most modern builds, JSON-LD is the practical choice. You can place it once per page and keep your structured data model aligned with the page’s server-rendered content. That helps when you have frequent template updates, multi-page CMS workflows, or a governance process for which schema types are allowed where. JSON-LD also reduces the chance of accidentally nesting markup incorrectly inside layout elements.
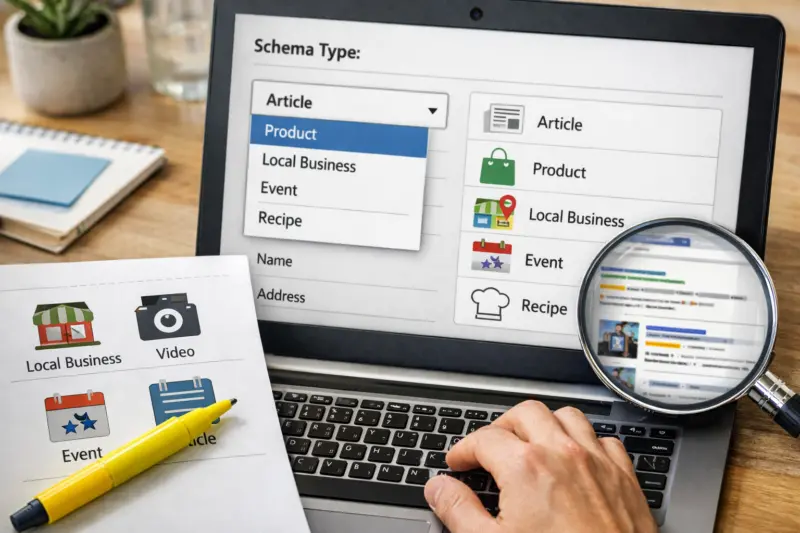
Microdata and RDFa can be useful for legacy systems or when the engineering team already outputs them with high consistency. The tradeoff is that they may require more careful template editing, and the markup can be harder to keep aligned as components change. If your site uses heavy client-side rendering, you still need to ensure the structured data is present in the version crawlers can read.
A controlled baseline can also be valid. If you cannot guarantee truthfulness for a specific page category, you may choose “no markup” or minimal markup for that segment. It can be better to omit structured data than to publish a misleading entity identity. This matters because schema that does not match the visible content can reduce trust in your structured signals.
An anti-pattern is mixing formats or duplicating contradictory properties. For example, placing two different identifiers for the same Organization across blocks on one URL can create ambiguity. Another anti-pattern is scattering properties for one entity across multiple markup blocks that do not clearly share the same entity context. Parsers may ignore one block, and you lose the clarity you tried to add.
To keep your approach grounded, review Google Search Central – Using structured data. It helps you align expectations for how Google reads structured data and why implementation quality matters. After changes, measure outcomes by validation success, crawl confidence, and changes in how search results present eligible structured content.
Common mistakes that prevent schema types from helping SEO
Schema does not help when it is inaccurate, mismatched to the page content, or incomplete in ways that break entity clarity. Many issues look fine at a code level but fail at an evidence level. That is why schema type selection must be paired with real page modeling.
The biggest misconception is that “more schema types equals better results.” Search engines prefer accurate, coherent meaning. If you label a category page as an Article, or tag a location page with the wrong address, you create structured contradictions. Even if parts validate, the overall entity interpretation can become ambiguous and the markup may not contribute.
Another major pitfall is missing required properties and then filling the gap with plausible guesses. For instance, adding a phone number that is not visibly published, or using an author name that differs from the byline, can make your markup less trustworthy. You also want internal consistency for identifiers across pages. If your Organization name changes between pages, crawlers may treat them as separate entities.
Coverage errors are also common. Applying schema to pages that are not indexed, are blocked, or are redirected can waste your effort. Pagination and canonicalization issues can also affect usefulness. Your structured data can be structurally correct, yet still not reflect the canonical content users and crawlers should treat as the main page.
Deeper nuance shows up with pagination and faceted navigation. If your page shows a list but your structured data describes a single item, you create a mismatch. Or if each paginated page repeats the same canonical URL identity, entity consolidation can become harder. The fix is not just technical, it is modeling: align the structured entity you describe with the dominant visible content.
One subtle implementation mistake is property placement and nesting. Some parsers treat improperly nested properties as belonging to the wrong entity. If you add “author” fields in one context but the schema type you selected expects them elsewhere, the meaningful part may not be linked. Validation tools can catch many issues, but they do not always guarantee usefulness.
Edge cases where choosing schema types gets tricky
Schema type selection gets difficult when a page legitimately contains multiple entities or frequently changing facts. In those cases, you need a strategy for choosing one primary subject and keeping secondary details optional and evidence-based. Robust schema modeling is about avoiding ambiguity.
Multi-entity pages are the first challenge. Imagine a page about a service hosted by your Organization, featuring a specific staff member, and linking to a featured case study. Your primary type should match the page’s main narrative. If the page’s main content is a service page, keep the primary entity service-related. You can reference Organization and Person as supporting entities only if the page clearly presents those identities and their attributes.
Data that changes frequently also creates risk. Pricing, availability, schedule, or operational status can shift quickly. Your structured data should reflect what is true at crawl time, not what was true when you built the template. If you show “From $X” on the page but your structured data includes a more specific price range that is not visible, you create evidence mismatch.
Author and identity complexity is another edge case. Some editorial workflows have multiple authors, editors, or guest writers. If you publish multiple bylines on the page, you may need a structured approach that represents those contributors accurately. If your site uses reusable author profile templates that do not match specific article facts, you might prefer limiting properties to what you can verify per page.
Local correctness can also break in subtle ways during replatforming. If your location pages update addresses but your structured data components still pull the old address from a legacy field, you publish contradictions. Even when validation passes, search engines may treat location identity as inconsistent. Keep location data centralized and ensure the canonical URL hierarchy matches the entity you describe.
A useful way to think about robustness is the difference between “valid” and “useful.” Validation checks syntactic correctness, but not whether the entity is clearly evidenced by the page. Parts of your markup can validate yet be ignored if the entity is ambiguous, redundant, or unclear in the primary page content. A common misconception is to treat a green validation status as completion.
Building a maintainable schema system across your site architecture
A schema system becomes valuable when it is governed, reusable, and aligned with your CMS content model. Instead of authoring schema once per page, you design templates and components that reliably output the right schema types for each page category. This is where teams prevent schema drift over time.
Start by mapping your CMS content types to schema type families. For example, an “Article” content type should consistently output Article or BlogPosting framing, and an “Author profile” content type should output Person where appropriate. If you have location landing pages in your CMS, those templates should output LocalBusiness with location fields that are sourced from the same content entry that powers the visible page.
Then create a property library. This is a set of fields and rules your developers can reuse, like a standardized way to output name, logo, and contact details for Organizations. For articles, standardize how you output publication and update dates, and how you represent authors. The library should include guardrails for missing data, so your templates do not guess when fields are absent.
Governance matters during migrations and redesigns. Canonical URLs, redirects, and restructured navigation can change which URL should represent the entity. If you move content to new templates without updating schema logic, you can silently break entity consistency. A maintainable approach ties schema output to canonical page logic and ensures structured data components follow redirect and template rules.
For testing discipline in 2026 workflows, use regression checks for your top templates. Validate a sample of URLs per template category after schema updates, not just once at launch. Monitor for structural-data drift when content editors change workflows, when developers refactor templates, or when new fields become available in the CMS. Validation errors are actionable, but warnings can also indicate partial entity loss.
Define realistic success criteria beyond “validation passes.” In a strong rollout, you keep entity identity consistent, ensure the markup matches visible content, and avoid frequent structural mismatches across templates. Structured data should remain truthful as the site evolves. That is the long-term SEO benefit of schema types implemented as a system, not as one-off code patches.
Frequently asked questions about understanding types of schema markup for SEO
What are the main types of schema markup, and how do I choose between them?
The main schema types map to the entity or content framing on your page, such as Organization, LocalBusiness, Person, and Article or BlogPosting. Choose the schema type that matches the primary subject your page presents to users, then include only properties you can evidence on the page. If you cannot reliably supply needed fields, use a broader but accurate type instead of guessing for a more specific one. This keeps your structured data aligned with visible content, which is where usefulness starts.
How do schema types differ from schema properties when planning implementation?
A schema type is the category that defines what your page represents, like Article or Person. Schema properties are the details you attach to that type, such as name, author, or datePublished. Planning works best when you choose the type first, then inventory which properties your CMS and templates can output accurately. This prevents teams from building an “almost right” set of fields around the wrong entity model.
Should every page on my site include schema markup, or only specific page types?
You do not need schema markup on every URL. It is often best to apply schema where the page contains a clear entity or content framing that users can understand and you can support with accurate fields. For example, author profile pages can use Person, while editorial pages can use Article. Applying schema to listing pages or category archives where the main content is not a single entity can cause mismatches.
What happens if the schema markup doesn’t exactly match the visible content?
If structured data does not match the visible content, it can create an evidence mismatch that reduces usefulness. Some issues show up as validation errors, but many mismatches still parse and may lead to underperformance. Search engines generally rely on what they can confirm from the page, so hidden or guessed properties can be treated as unreliable. The safest rule is to keep schema truthful to what the page visibly supports.
Can I use multiple schema types on the same URL without confusing search engines?
You can, but you should avoid contradictions and keep a clear primary subject. Use one main schema type that best matches the dominant content framing on the page, and treat other schema entities as supporting context when the page explicitly supports them. If you include multiple primary types, or if identifiers conflict, you can create ambiguity. A structured approach helps keep entity relationships coherent.
How do I validate that my schema implementation is correct in 2026 workflows?
Start with structured-data validation tools to catch syntax and basic structural issues, then verify the markup aligns with the visible content on the live page. In 2026 workflows, add regression checks for your main templates after schema changes. Also compare the canonical and rendered content for paginated or templated URLs, since mismatches often come from how the page is assembled. Validation is necessary, but usefulness requires evidence alignment.
What’s the difference between Organization and LocalBusiness schema types for SEO purposes?
Organization describes a broader company identity, while LocalBusiness describes a local operating entity with place-based details. Use LocalBusiness when the page represents a specific location or service presence and you can provide consistent address and contact signals. Use Organization for brand identity pages that do not focus on a distinct location entity. The key difference is whether the page supports location-specific evidence.
When should an SEO team prefer JSON-LD over other schema implementation formats?
Most teams prefer JSON-LD because it is easy to generate consistently and keep separate from page layout markup. It also fits well with template-driven CMS systems where you want structured data to update reliably without scattering markup through HTML. Microdata or RDFa can work, but they often require more careful template coupling and can be harder to maintain during redesigns. Choose the format your engineering workflow can keep accurate and consistent over time.
How can we prevent schema drift when CMS templates or content templates change?
Prevent drift by tying schema output to your CMS content types and component libraries, not by editing schema ad hoc per page. Add regression testing for key templates so changes to fields, layouts, or canonical logic trigger a validation and evidence review. Use governance rules that define which schema type families apply to which page categories. Version structured-data components so you can roll forward intentionally and avoid silent mismatches.
How do schema types work for content like FAQs, guides, or help-center articles?
For FAQs and help-center content, schema should match how the page frames the content to users. If the page is a standalone guide or article with clear titles and bylines, an Article or BlogPosting framing can fit. If the page uses a question-and-answer structure, you may represent that structure with appropriate FAQ-style modeling when it matches the actual content. The core rule stays the same: properties must reflect what is visible and the schema type must match the page’s main framing.
Conclusion: schema types are a modeling decision, not a one-time checklist
The best way to understand types of schema markup for SEO is to treat schema types as a modeling choice tied to page intent and the main entity. Start by identifying what the URL is truly about, then select the schema type family that matches that framing. After that, add only properties you can support with accurate, visible evidence.
When you implement this workflow, schema becomes easier to maintain. You reduce mismatches, avoid contradictory entity identities, and keep structured data aligned during template changes and content updates. That maintainability matters in 2026 because CMS-driven sites evolve constantly, and schema that drifts stops being trustworthy.
If you want a practical next step, audit a small set of high-impact templates first. Document your schema mapping rules from page goal to entity type, then implement using a consistent component approach. Expand rollout only after regression checks confirm that your markup stays truthful and structurally sound as your site changes.
Updated September 2026