You design website structure to grow without turning every new feature into a rewrite. That means planning information architecture, routing, data models, deployment boundaries, and governance from day one. In this guide, we cover website architecture best practices that keep your team moving as traffic, content, and product needs expand. For 2026, the real goal is change-friendly scaling, not just meeting a performance target. This guidance is for web designers and developers building content- and product-driven sites like marketing platforms, portals, eCommerce-like experiences, and SaaS marketing plus app ecosystems. As you grow, “scalable” should mean reliable releases, predictable operations, and clean evolution paths.
Contents
- 1 Turn scalability goals into architectural decisions before you write templates
- 2 Design information architecture so growth doesn’t break navigation or SEO
- 3 Set modular front-end and back-end boundaries that scale with teams
- 4 Build data and content pipelines that stay reliable as volume increases
- 5 Create deployment and environment strategies for safe frequent growth
- 6 Avoid architectural failure modes that appear only after the site grows
- 7 Choose scalable architecture options based on constraints, not trends
- 8 Handle migrations, replatforming, and long-lived URLs without losing SEO value
- 9 Frequently asked questions about website architecture for scalability
- 9.1 What does scalable website architecture include beyond page speed?
- 9.2 How do I structure URLs and navigation for long-term scalability?
- 9.3 When should a site move from a modular monolith to more separated services?
- 9.4 How can we prevent taxonomy drift when many editors add content over time?
- 9.5 What’s the best way to model content types so new features don’t require rewrites?
- 9.6 How do contract tests and API versioning support scalable architecture?
- 9.7 What should staging vs production parity checks include for a scalable setup?
- 9.8 How do we migrate long-lived URLs without losing SEO value during replatforming?
- 9.9 How do feature flags help scaling architecture across multiple modules?
- 9.10 What are the most common architecture mistakes that only show up after scaling traffic?
- 9.11 Is headless always more scalable than a traditional CMS-driven approach?
- 10 Conclusion
Turn scalability goals into architectural decisions before you write templates
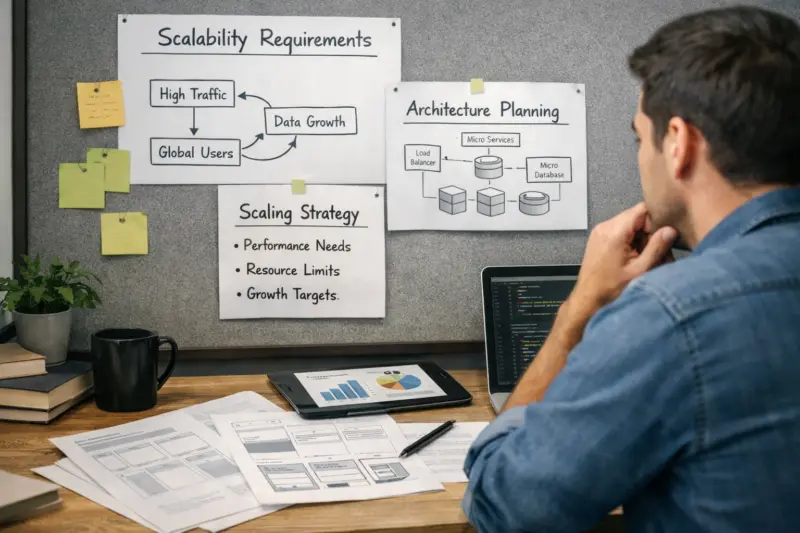
Scalability starts with requirements, not with frameworks or folder structures. If you define what must grow, you can choose boundaries and contracts that survive change. This prevents the classic rework loop where you rebuild URLs, data schemas, and deployment pipelines after the site becomes complex. In practice, website architecture best practices begin with an intake that translates business and content growth into technical constraints.
First, gather scalability requirements in plain terms. Estimate traffic and user behavior growth, not just peak load. Forecast content growth, including how many new categories, landing pages, and media assets editors will add. Then account for team growth and workflows, like how many reviewers will approve content per release. Also note geo expansion, since multi-region delivery and localized content change routing and data boundaries. Finally, identify security and identity complexity, since authentication often grows from “optional” to “mission critical” as you add gated pages.
Next, translate those requirements into architecture constraints. SEO needs affect URL strategy, template rules, canonical behavior, and internal linking paths. Editorial workflows affect data modeling, publish states, and moderation queues. Personalization affects caching rules and response shaping. Authentication complexity affects session management, access control boundaries, and how you model user-specific data. Media types affect asset pipelines and how rendering logic loads and caches content components.
Now use a decision path that locks in safe structure early. Pick boundaries first, like domain areas or feature modules. Then define contracts between boundaries, such as page templates, resource models, and APIs. Treat this like “designing interfaces,” not “designing screens.” This keeps modules evolvable while letting your team ship frequently.
Be careful about future-proofing theater. If you split everything too early, you create fragmentation without real independence. A simple test helps: measure coupling and migration effort. If changing one module forces redeploys across most pages, your boundaries are not real. If a migration would require rewriting content and templates across many areas, your structure is brittle. Premature modularization often looks clean in diagrams, yet it fails during real feature work.
Consider a real scenario: a marketing site adds a new program landing area every quarter. If your taxonomy and routing are flexible, you add new sections without breaking old pages. If they are hard-coded into templates and business logic, editors trigger redirects, index churn, or broken navigation after each launch. The difference is usually made before templates are built, not after.
Information architecture must evolve without destabilizing URLs, navigation, and search indexing. When your content structure is designed for growth, SEO stays consistent as new categories appear. This is one of the most important parts of scalable website architecture because editors and features change over years. If your structure “only works today,” it will break during the next growth wave.
Start with content modeling fundamentals. Define taxonomies that represent the real concepts your users search for. Then define page templates that map those concepts to stable page patterns. Use component roles to separate “what the page is” from “how it looks.” For example, a “program overview” template can reuse common components like benefits, FAQs, and related programs while changing only the content model behind the sections. This approach reduces template churn when you add new content types.
Next, structure URLs and routing to accommodate new landing pages. Create routing rules that support new categories without forcing redirect chains. Prefer predictable, hierarchical URL patterns where possible. Also plan canonical behavior so you can avoid duplicate indexing when multiple filters or localized variants exist. If you introduce new URL segments later, your redirects must be deliberate and measured, not ad hoc.
Multilingual and multi-region content adds real IA complexity. Plan how you represent language, locale, and region in your content model. Use a controlled approach to avoid inconsistent taxonomy labels across languages. Otherwise, you end up with uneven indexing and mismatched internal navigation. In multi-region setups, decide which content fields differ by region and which remain shared, so you do not fork models unnecessarily.
Governance is what keeps your IA stable under constant editing. Set editorial rules for when to create a new section versus when to extend an existing one. For example, if a new program fits an existing taxonomy facet, add it there. If it truly represents a different user journey, create a new top-level concept with clear ownership. Also define who can introduce new labels and when the taxonomy review happens.
A subtle edge case is taxonomy drift. Over months and years, editors may create inconsistent labels that look similar but differ in spelling or intent. This drift breaks faceted navigation, confuses internal linking, and can cause indexing fragmentation. It also creates duplicate content patterns when pages are generated from inconsistent filters. A good system catches drift through validation rules and monitoring checks that compare taxonomy usage over time.
Common mistake: assuming taxonomy drift is “just an editorial issue.” In reality, it impacts indexing, internal link targeting, and how users discover pages. Therefore, treat taxonomy governance as an architecture concern, not a spreadsheet chore.
Set modular front-end and back-end boundaries that scale with teams
Scalable architecture needs modular boundaries that let teams work independently. If modules share logic and data too tightly, every change becomes a cross-team event. As a result, releases slow down and risk rises. Clear boundaries help you ship safely while the system grows in features and content types.
Think in domain boundaries, not just UI components. A shared “header component” is not a boundary by itself. A useful boundary is a domain area that owns a coherent set of resources, workflows, and rendering rules. For example, a “user account” domain owns profile views, preferences, and access control checks. A “catalog” domain owns program listings, filters, and program detail rendering. This domain thinking reduces hidden dependencies.
On the front end, use patterns that make rendering predictable. Define a clear contract between the content model and the components that render it. Then make feature modules responsible for their own templates or renderers. This lets you add new page types without editing core layout logic for every change.
On the back end, establish data ownership boundaries. Design APIs around resources, not around internal database structures. Resource modeling helps keep module evolution safer. It also reduces the temptation to let one module directly query another module’s schema. When APIs form clean contracts, you can version them and roll out changes with less fear.
Operational scalability is part of the boundary story. Each module should have observability points. That means logs and metrics that identify which module produced an error or slow query. It also means error handling boundaries that prevent one module failure from cascading across the site. Add rollback safety by ensuring each module can revert without breaking shared pages.
A common limitation is the shared database trap. Teams may split code into modules but still rely on one evolving schema. When everything touches the same tables, schema changes require coordinated releases. That defeats modularity and increases the chance of broken rendering. Therefore, ensure boundaries extend to data evolution, not just repositories.
For example, if the “content” module and the “search” module share the same taxonomy tables, a taxonomy change can break both areas at once. Instead, consider data synchronization with explicit ownership or a controlled read model. That keeps the system resilient during growth.
Build data and content pipelines that stay reliable as volume increases
Scalable pipelines keep content stable as volume grows and schemas evolve. Without a reliable pipeline, you will face broken templates, inconsistent renders, and hard migrations. Pipeline design also affects operational clarity, because failures become easier to trace. This is a core part of website architecture best practices, especially for content-heavy sites.
Start with data modeling that supports evolution. Decide what you write frequently versus what you read heavily. Use normalization where it reduces duplication and clarifies ownership. Use denormalization carefully where it improves read paths. However, avoid spreading update logic across modules without a clear contract. If two modules update the same fields in different ways, “eventual consistency” turns into silent data corruption.
Next, design publish states and content workflows. Represent draft, review, and live states explicitly. Then ensure the pipeline processes those states idempotently. Idempotent processing means repeating the same job does not create duplicate outputs. This matters when retries happen due to temporary failures. For example, a media reprocessing job should not create multiple versions of the same asset.
Plan migration readiness as part of the pipeline, not a separate project. When you add fields or new entities, older templates and older API consumers must not break. Use compatibility layers and versioned parsing so old content can still render. Also plan backfills for historical content when taxonomy or structure changes. This prevents half-updated pages that harm SEO and user trust.
Edge case: historical content tied to old taxonomy rules. When you change labels, you may need to remap older pages to the new taxonomy. You also may need to re-index internal references so internal navigation remains consistent. Media asset reprocessing can also reveal hidden coupling, like a renderer expecting an asset with a specific aspect ratio. Therefore, include pipeline checks that validate assumptions before publishing.
Common mistake: treating migrations as one-time scripts. In scalable architecture, migrations are part of continuous delivery. You need repeatable steps, rollback plans, and checks that verify the system can render both old and new variants during transitions.
Create deployment and environment strategies for safe frequent growth
Safe growth requires deployment strategies that reduce risk and make failures reversible. If releases are fragile, scaling becomes scary. Therefore, deployment architecture is a scalability lever, not an afterthought. It supports change management as your site adds features, modules, and content templates.
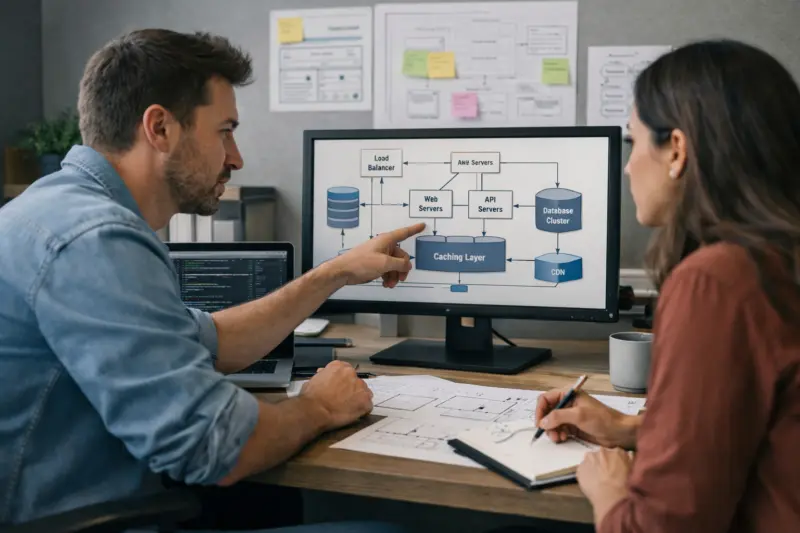
Begin with environment architecture best practices. Use dev, staging, and production with close parity. Configuration differences often hide issues until production. Also handle secrets safely and avoid “works on staging” failures caused by missing credentials or different access rules. Deterministic builds help , since you can reproduce the same artifact across environments.
Release strategies should align with module boundaries. Blue/green deployments can reduce downtime for major changes. Canary-style rollouts can limit exposure by routing a small slice of traffic to a new module version. Feature flags help you separate code deployment from behavior release. However, flags must map to real boundaries so you can retire them cleanly. Flag debt creates complexity that hurts long-term scalability.
Operational scalability also includes the deployment pipeline itself. As teams grow, the pipeline must run reliably across multiple runtimes and versions. Add automated checks that validate schema changes, contract compatibility, and dependency graphs. Contract checks are especially important when modules evolve independently. They catch breaking changes before they reach production.
A deeper nuance is environment-specific routing and CDN behavior. Routing rules might differ between staging and production due to proxies or rewrite settings. Similarly, caching headers and cache invalidation behavior can change across environments. These differences can break rendering or SEO behavior in ways that look like “random bugs.” Therefore, test routing and caching behaviors as part of automated checks.
Failure mode: a change passes staging because staging lacks a specific integration. In production, the integration responds differently and breaks rendering. To prevent this, use integration readiness checks that confirm required dependencies are present and behave as expected.
Avoid architectural failure modes that appear only after the site grows
Many scalability problems show up only after real growth stress hits. At that point, fixes are expensive. You can prevent most late failures by recognizing common architectural failure modes early. This section covers the patterns that usually cause slow releases, broken navigation, and data inconsistencies.
One major pitfall is tightly coupled page templates and business logic. When templates embed business rules, you end up redeploying the whole site for small changes. That slows growth and raises risk. Instead, keep business logic inside modules and make templates focus on mapping content to presentation. This separation also makes it easier to update behavior without touching every page type.
Another pitfall is ad hoc taxonomy and URL additions. Editors or developers sometimes add categories without governance. Over time, URLs proliferate, redirects accumulate, and internal links break. Index volatility follows, since search engines see many shifting signals. Therefore, treat taxonomy and routing changes like controlled architecture changes, not quick content tasks.
Inconsistent data schemas cause silent corruption. If you do not version data models and rendering contracts, old pages can render incorrectly. Worse, the system might fail only for specific content variants. That makes debugging difficult and risks damaging user trust. To prevent this, use schema evolution tactics and compatibility strategies that keep older variants renderable.
Ignoring governance becomes a scaling killer. Without an ownership model for modules, taxonomy, and shared components, teams duplicate work. They also introduce incompatible changes that look fine in isolation. Over time, drift creates more maintenance than new feature work. Therefore, define ownership and review paths for architecture-impacting changes.
A deeper insight is the “monolith without structure” scenario. You may have one repo, but the real problem is missing boundaries. When code lacks domain separation and clear contracts, your monolith acts like a tightly coupled system. Scaling then fails at the architecture level, not the infrastructure level. You might also see that scaling “infrastructure” alone does not solve release risk or data evolution issues.
Practical scenario: you add ten new page templates, but each requires editing shared utilities. Eventually, every template change forces risk across the site. This is how coupling turns into release paralysis. The fix is boundary design and contract clarity, not more templates.
Choose scalable architecture options based on constraints, not trends
Scalable architecture is a set of tradeoffs, not a single winning pattern. You need to choose an approach that fits your content workflows, team skills, and operational tolerance. For 2026, most teams land in hybrid realities. Therefore, evaluate architecture categories by how they handle change over time.
Consider these four common options. First, a CMS-first approach with templated pages and modular plugins can work well for marketing sites. It often supports editorial workflows quickly and keeps rendering consistent. However, you must still design governance for templates, taxonomies, and content types so that growth does not fragment the system.
Second, a component-driven front end with API-backed content rendering can scale well for product-like experiences. This pattern clarifies contracts between content services and rendering modules. The tradeoff is more engineering effort to model resources and handle caching and personalization logic.
Third, headless or decoupled content separates presentation from content services. This can help when you have multiple clients and complex editorial needs. Yet, it increases operational overhead. You must manage more moving parts, including content delivery, caching rules, and indexing consistency.
Fourth, a modular monolith with clear domain boundaries is an incremental path that suits teams that want structure without service sprawl. It can improve independent releases within one deployable system. The risk is the shared database trap if boundaries do not include data ownership and migration strategy.
Use a choice matrix to compare tradeoffs clearly. Time-to-market matters, but so does migration complexity. Team skills matter too, because architecture only scales when people can maintain it. Editorial workflows are often the decisive factor, especially for content-heavy sites. Operational burden also matters, since observability, rollbacks, and contract checks require ongoing effort.
A hybrid trap can hurt scalability. Teams sometimes combine patterns inconsistently, like using decoupled rendering but keeping shared schema access and ad hoc taxonomy changes. That creates unclear ownership and duplicated sources of truth. Therefore, align your choice across routing control, content modeling flexibility, contract stability, and observability. Those are the factors that protect you during growth.
| Approach | Best fit | Main scalability tradeoff |
|---|---|---|
| CMS-first | Editorial-heavy marketing sites | Governance and template sprawl |
| Component + API | Product-like pages with stable contracts | More engineering for modeling |
| Headless/decoupled | Multiple clients and complex delivery | Higher operational overhead |
| Modular monolith | Independent teams without service sprawl | Shared schema coupling risk |
Finally, decide “stay simpler” versus “split modules” using decision triggers. Multiple teams with frequent releases often justify more modular boundaries. Domain volatility also pushes you to separate contracts. If you are still stabilizing taxonomy and user journeys, resist unnecessary splitting and focus on governance and contracts.
Handle migrations, replatforming, and long-lived URLs without losing SEO value
Long-lived URLs and safe migrations are essential for scalability. As your site grows, you will change templates, move platforms, and refine content models. If you plan migrations well, you preserve indexing signals and avoid broken internal navigation. This is where scalable architecture and operational discipline meet.
Plan URL longevity from the start. Decide how you will map content concepts to stable URL patterns. When you must change structure, create a redirect strategy that preserves user experience and search signals. Also define canonical rules that avoid duplicates during transitions. Internal linking integrity matters too, because internal links influence how search engines discover and understand relationships between pages.
When replatforming, protect your rendering contracts and page outputs. Keep content states consistent so published pages remain correct after the migration. If you move from one rendering strategy to another, validate that page templates produce equivalent HTML structure, metadata, and content mapping. Otherwise, you risk index churn caused by subtle output differences. For guidance on how search engines interpret canonical and duplicate patterns, see Google Search Central and Google Search Central: Duplicate content.
Handle long-tail content carefully. Archived pages, seasonal landing pages, and older program variants often rely on older schemas. If you only migrate “current” content, old pages may break or render incorrectly. Therefore, maintain backward compatibility for older page variants during the transition period. You may also need batch reprocessing for older media assets if new rendering logic expects different formats.
For API and data model breaking changes, use versioning and deprecation timelines. Treat breaking changes like product launches. Announce an adoption window, then update templates and clients in phases. During the overlap, your system must render both old and new variants. Otherwise, you will see partial failures that harm user trust.
A subtle edge case is editorial workflow changes during replatforming. New template rules can alter page output even if content stays the same. That can change metadata, headings, or section ordering at scale. Search engines and users then see a large shift across many URLs. To avoid this, test template output diffs on real content samples and validate the change impact before you migrate.
Finally, monitor migration health like an operational release. Track redirect success rates, indexing signals, and render error rates. Ensure you can roll back quickly if a mapping rule fails. Scalability includes the ability to recover fast when a migration goes wrong.
Frequently asked questions about website architecture for scalability
What does scalable website architecture include beyond page speed?
It includes maintainability, modularity, deployment safety, and reliable data evolution. You also need operational scalability, meaning observability and rollback safety across modules. In other words, it should help your team ship changes without breaking existing pages.
Use URL patterns that map cleanly to your content model and taxonomy. Then govern taxonomy changes so new categories do not create inconsistent labels or redirect chaos. During growth, keep canonical rules and internal linking stable to avoid index volatility.
When should a site move from a modular monolith to more separated services?
Move when you have multiple teams needing independent releases and clear ownership boundaries. Also do it when domain volatility and contract complexity justify service separation. If your shared data model still couples modules strongly, splitting services first can increase migration risk.
How can we prevent taxonomy drift when many editors add content over time?
Use controlled vocabularies, validation rules, and workflow reviews for label changes. Also add monitoring that detects inconsistent taxonomy usage across months. When drift is detected, remap and backfill older content to keep navigation and indexing coherent.
What’s the best way to model content types so new features don’t require rewrites?
Model content types around stable concepts and user journeys, not around current UI layouts. Then map templates and components to the content model through clear contracts. Plan schema evolution with compatibility so older page variants still render after updates.
How do contract tests and API versioning support scalable architecture?
They prevent breaking changes by verifying that modules still satisfy their interfaces. Versioning gives you an overlap window where old and new consumers can coexist. This reduces release risk and supports independent module evolution.
What should staging vs production parity checks include for a scalable setup?
Check configuration parity, routing and rewrite rules, and caching behavior. Also validate integrations and secrets readiness so staging failures match production conditions. Finally, run deterministic build and schema or contract checks before deploy.
How do we migrate long-lived URLs without losing SEO value during replatforming?
Create a redirect plan that covers every old URL mapping with correct status behavior. Then align canonical rules and template output so pages remain equivalent in intent and structure. Monitor render and indexing health during phased migration, and keep rollback ready.
How do feature flags help scaling architecture across multiple modules?
Feature flags let you ship code safely while controlling behavior at runtime. They also support gradual rollout per module, which reduces blast radius during architecture changes. Use flags aligned to module boundaries so you can retire them without long-term complexity.
What are the most common architecture mistakes that only show up after scaling traffic?
Common issues include hidden coupling, untested schema evolution, and missing observability. Caching and query hotspots can also surface when volume increases. Without architecture-aware monitoring, failures look random and recovery slows down.
Is headless always more scalable than a traditional CMS-driven approach?
No. Headless can scale well when your content workflow and team skills justify the added operational overhead. A CMS-driven approach can be highly scalable if governance, routing, and data contracts are designed for growth. The right choice depends on content modeling and change management needs.
Conclusion
Scalable website architecture comes from decision processes, not one-time checklists. Start by aligning scalability requirements to boundaries, contracts, and governance. Then stabilize your information architecture so navigation and SEO do not fracture as content grows.
Next, design modular contracts that let teams scale without creating hidden coupling. Build reliable pipelines that support publish states, schema evolution, and safe migrations. Finally, set deployment strategies that make frequent growth reversible and observable.
If you want a practical next step, audit your current setup against your boundaries, taxonomy governance, module contracts, and migration readiness. Map your constraints, like your team size, release cadence, and content workflow maturity, to the most fitting architecture option. Then treat website architecture best practices as an evolving system that you refine with each growth cycle.
Updated September 2026